parallel · lift
ECCV 2026 · 2nd author
Gripper-aware VLA
A Vision-Language-Action model that conditions manipulation on gripper morphology. I co-designed the gripper-conditioning module, implemented and ablated its variants, and co-wrote the paper.
CMU · M.S. AI Engineering · Robotics & Embodied AI
Research depth · GVLA, ECCV 2026 (2nd author); studying VLA generalization and decision-making.
Real-world robotics · Franka / UR5 evaluation and 50+ SO-101 demonstration episodes.
Engineering · Control, embedded hardware, simulation, and full-stack software.
I'm Zihong Luo (Logan), an M.S. AI Engineering student at Carnegie Mellon University working across robotics, embodied AI, and machine learning systems: from what VLM and VLA representations encode, to the controllers and robots that act on them.
The whole system as one stack: four layers, 13 parts.· scroll to take it apart
INTERACTIVE EXHIBITS
ECCV 2026 · 2nd author
A Vision-Language-Action model that conditions manipulation on gripper morphology. I co-designed the gripper-conditioning module, implemented and ablated its variants, and co-wrote the paper.
Planning & control · live demo
A* global routing and MPPI local avoidance on an endless street grid, with LiDAR ray casting, occlusion, and real-time replanning around closures.
Independent build · ESP32-S3 · C++
Two BLDC wheels, two servo-driven five-bar legs, an MPU6050 IMU on an ESP32-S3. Built on the StackForce platform: five-bar IK, cascaded PID balance, and roll-based terrain adaptation. Drive a simulated version across an endless skatepark.
ONGOING · CMU
How do pretrained vision-language models encode space and physics, and does that knowledge reach the actions a robot takes? My work follows one loop:
01Observe
Camera views, an instruction, and the robot state. In LIBERO I build counterfactual scene pairs that differ in one geometric factor.
02Represent
Pretrained VLMs such as Qwen3-VL produce visual-language features. The open question: do they encode spatial and physical structure, and does it survive into a VLA policy? Measured with representation probes.
03Act
A VLA maps those features to robot actions. In GVLA the policy is also conditioned on gripper morphology, so one model can adapt its strategy to the end-effector.
04Validate
Activation interventions test whether a representation actually changes the action; rollouts in simulation and on Franka / UR5 measure task success.
The CMU work is in progress: these are the questions and methods, not yet findings.
* EQUAL CONTRIBUTION
Selected for relevance to my current research. See the complete record on Google Scholar.
Hanyi Zhang*, Khang Nguyen, Charith Munasinghe, Basu Hela, Tianyu Li, Zihong Luo, et al.
Yiheng Zhong*, Zihong Luo*, et al.
Chengzhi Liu*, Zile Huang*, Zihong Luo, et al.
Zihong Luo*, Chengzhi Liu*, et al.
Under review
..., Zihong Luo, et al.
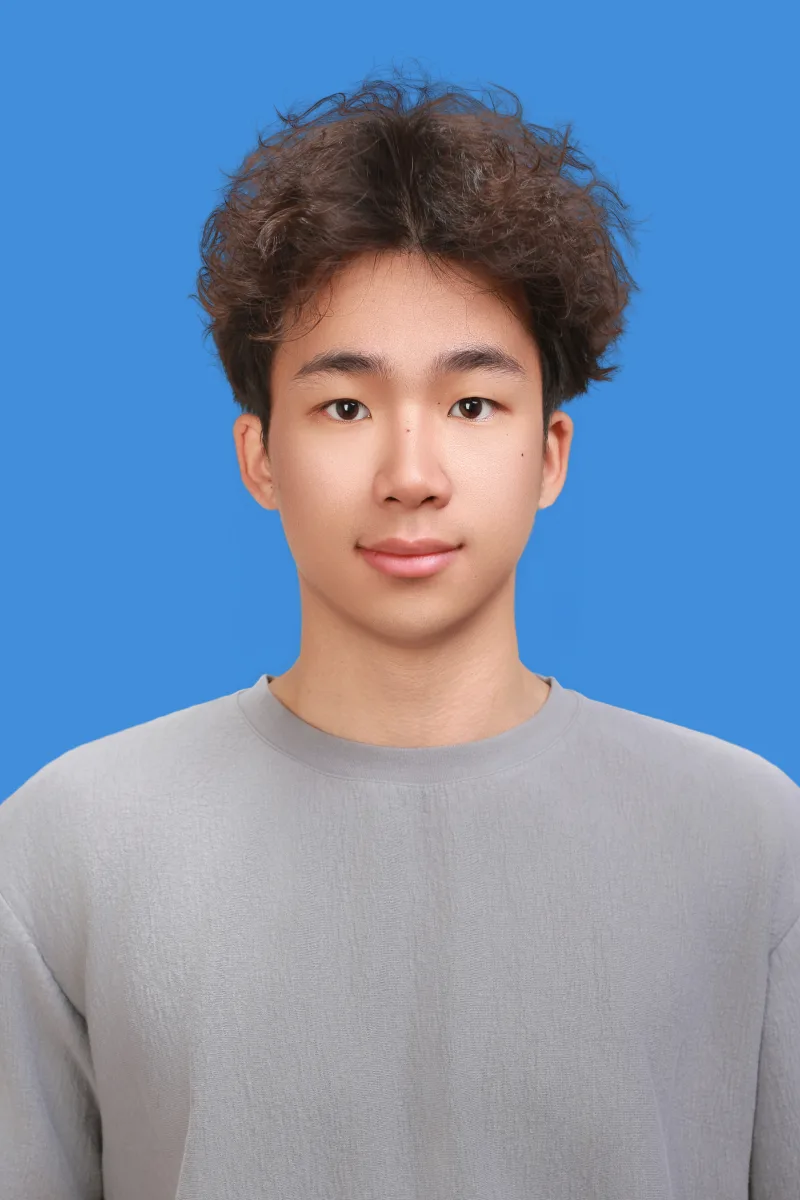
Lead Student Researcher with Prof. Guannan Qu at CMU. Before that, research assistant at SmartLab, University of Liverpool, with Prof. Anh Nguyen, and BSc in Computing Science (AI) with First Class Honours. The question connecting my recent work is how multimodal robot policies can adapt to different grippers, tasks, and real-world execution constraints.
Recent
Carnegie Mellon University
Pittsburgh, PA, USA · Advisor: Prof. Guannan Qu
Jifu Medical (AI Algorithm Group)
Shenzhen, China
MBZUAI
Abu Dhabi, UAE · Advisor: Prof. Imran Razzak
University of Exeter
Exeter, UK · Advisor: Prof. Yanda Meng
Tongji University School of Medicine
Shanghai, China · Advisor: Prof. Xiaoyun Xie
XJTLU
Suzhou, China
M.S. in AI Engineering - ECE
Pittsburgh, PA, USA
BSc in Computing Science (AI) | GPA: 3.9/4.0 | First Class Honours
Liverpool, UK
Open to research collaboration and Summer 2027 internships in robot learning, VLA models, and robotics systems.